Video Object Segmentation With XMem and Segment Anything
 Max KolomeychenkoUpdated
Mask an object on the first frame with Segment Anything, then let XMem track it through the whole video. Setup steps for video labeling in Supervisely.
Video object segmentation (VOS) marks every pixel of a target object in every frame of a video. This guide combines two models in the Supervisely video labeling toolbox: Segment Anything masks the object on the first frame, and XMem tracks that mask through the rest of the video. You then correct the result by hand. For one model that does both, see the SAM 2 guide.
Here is what the XMem model provides:
-
According to the paper, it greatly exceeds the state of the art on long-video datasets and is on par with state-of-the-art methods on short-video datasets.
-
Its memory consolidation keeps GPU memory use limited on long videos. The authors' repository reports about 20 FPS, depending on hardware.
-
It is designed for hard cases such as occlusion, objects leaving the frame, and changes in shape and view.
Video tutorial: how to combine SAM and XMem
The video shows how to combine the following three Computer Vision tools into a single workflow and achieve fast accurate segmentation of objects on videos:
-
Segment Anything model (SAM) to automatically annotate the first frame
-
XMem model to predict the given masks on the next frames
-
Video Labeling toolbox to connect models together and provide interactive user-friendly GUI for labeling automation, manual verification and correction
What is Video Object Segmentation (VOS)?
Video Object Segmentation (VOS) is a computer vision task where the goal is to highlight (segment) all pixels of specific target objects throughout all frames in a given video.
In the computer vision community, this task is often referred to as Semi-Supervised VOS where the user provides the annotation of objects on the first frame and the neural network tracks and segments these objects in all other subsequent frames as precisely as possible.
This approach allows to segment and track any objects on videos even the custom ones. So you can use any class-agnostic model for fast object segmentation (e.g., Segment Anything) for labeling objects of interest on the first frame and then the XMem class-agnostic masks tracking model will segment these objects on the next frames.
What is the XMem model?
XMem neural network is a video object segmentation architecture for long videos with unified feature memory stores. The model is class-agnostic which means that it can track masks for any objects. The model can 'memorize' an object and continue to segment it even after the object leaves the video scene for some time. It is also good at handling complex scenes with object occlusions and changes in shape and view.
Here is the authors' demo video:
The model is implemented to deal with both single and multiple objects on long videos. It is the first multi-store feature memory model used for video object segmentation. It was introduced at European Conference on Computer Vision (ECCV) in 2022.
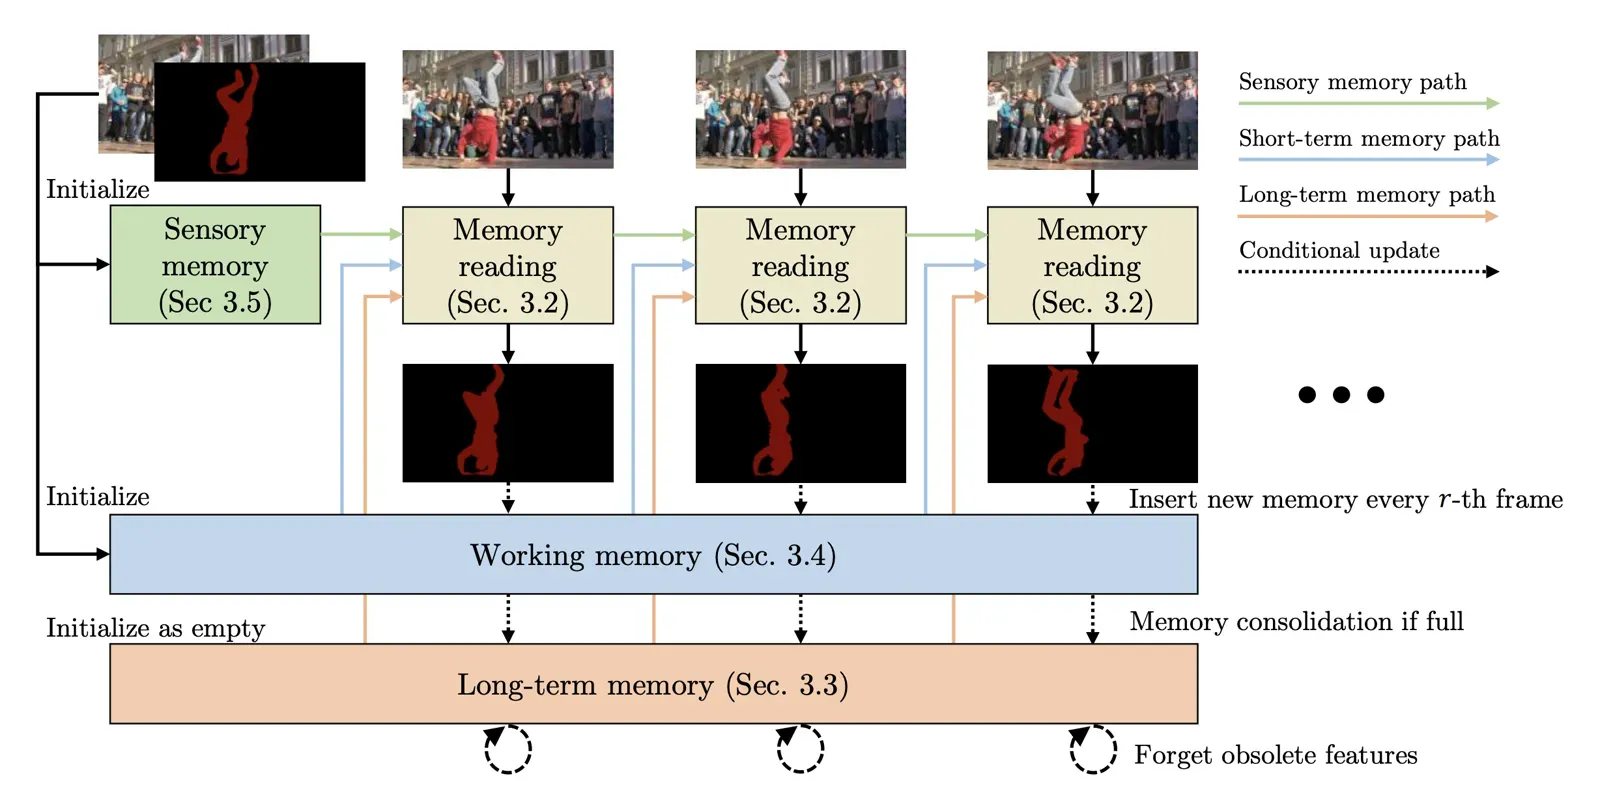 XMem architecture overview. The memory mechanism gets relevant features from all three different types of memory stores and predicts the object mask based on them. The sensory memory updates every frame, and the working memory updates every n-th frame. Long-term memory is a compact representation of the working memory.
How to do video object segmentation step by step
Follow the steps below to reproduce the video tutorial on your data in Supervisely. The video tools are covered in the docs. For other trackers and how they compare, read the object tracking guide.
What you need: a Supervisely account (the free Community Edition works) and a computer with a GPU.
- Connect your GPU to Supervisely (one time).
- Run Segment Anything to mask objects on the first frame.
- Run XMem to track those masks.
- Segment and track objects in the video labeling toolbox, then review the masks.
Step 0. Connect your GPU to Supervisely
This is a one-time procedure, just skip this step if you already did that.
With a single command executed in the terminal, you can connect your personal computer with GPU to the Supervisely account and run on your machine any apps that require a video card. You can connect multiple computers and it will allow you to horizontally scale computational resources for your experiments. To learn more watch this 1.5-minute how-to video.
Step 1. Run Segment Anything model (SAM)
In the video tutorial, we deploy and use Segment Anything interactive segmentation model to fast objects segmentation on the first frame. Just run the app, select one of the ready-to-use pre-trained models and press Deploy button in the GUI.
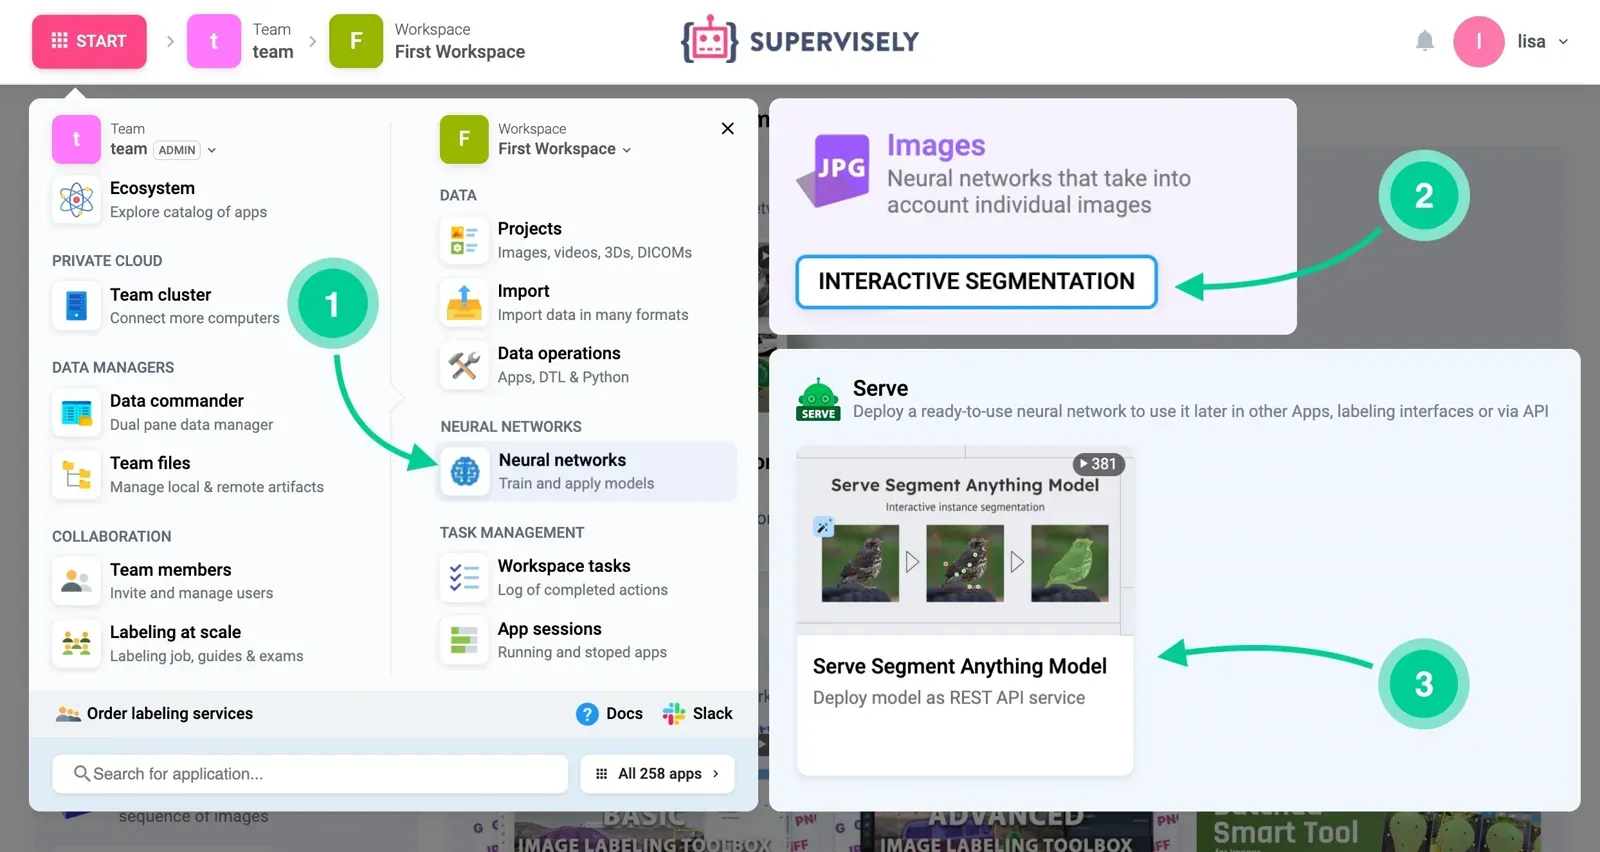 Go to Start → Neural Network → Interactive Segmentation.
Interactive segmentation allows users to provide feedback for the model by putting positive and negative points on the image. It helps the model to segment the object inside a bounding box and explicitly control the predictions. Such interaction makes it possible to select an object of interest and correct prediction errors.
The demo video below illustrates how simple and fast it is to segment objects using AI assistance. You can apply any interactive segmentation model either for images or videos in Supervisely.
Enterprise Edition: By default, the administrator of your Supervisely instance deploys one or several interactive segmentation models and makes them available for all users on the instance. If the model has not started yet, just run it yourself or contact your instance administrator.
Step 2. Run XMem model
Run the XMem serving app on the computer with GPU.
XMem Video Object Segmentation
Semi-supervised, works with both long and short videos
Click Start button → go to Neural Networks page → Video segmentation section and run the XMem model on your computer with GPU:
Step 3. Segment and track objects on videos
Now you can go to the video labeling toolbox, select one or several objects and track selected masks on the next frames.
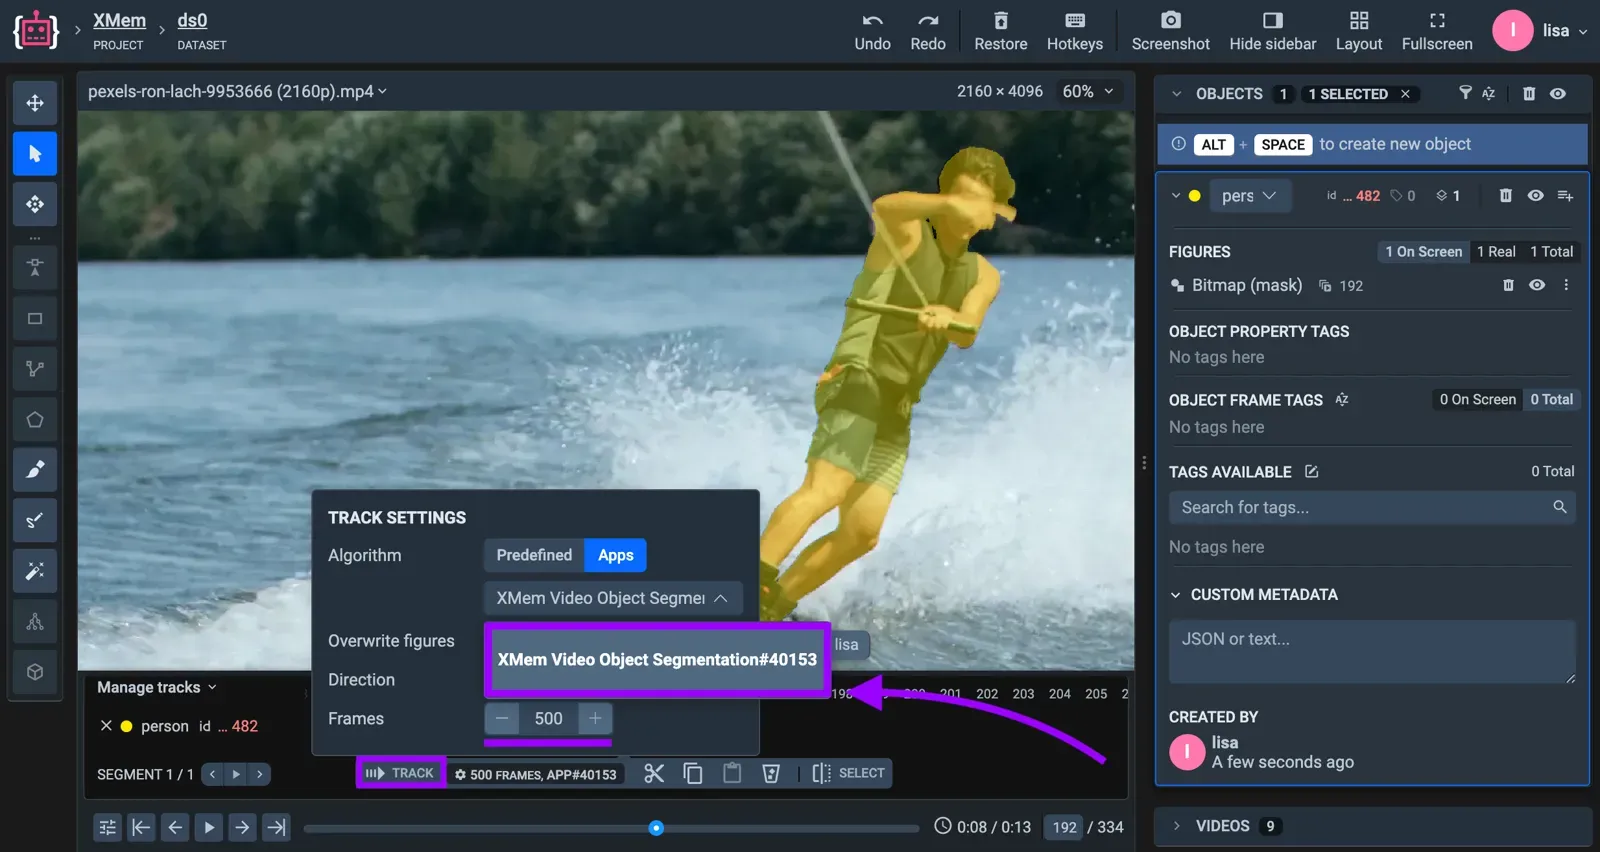 Select the tracking algorithm and press "Track" button on the video timeline.
How well does XMem work on long videos?
In our tests XMem worked well on videos with occlusions and shape changes, and it can keep following an object over a long video. Masks still need review: check them frame by frame and correct the ones that drift.
XMem vs SAM 2: when to use which?
Use XMem with Segment Anything when you want a two-step workflow with a tracker you can deploy yourself: Segment Anything makes the first-frame mask, XMem follows it. Use SAM 2 when you want one model that takes a click, box or mask on any frame and tracks the object. Facts below are from the XMem repository, the XMem paper and Meta's SAM 2 page.
| Segment Anything + XMem | SAM 2 | |
|---|---|---|
| Models needed | Two: Segment Anything for the first frame, XMem for tracking | One |
| Prompts | Masks on the first frame; XMem tracks them | A click, box or mask on any frame, refined with more prompts on any frame |
| Memory | Sensory, working and long-term memory stores | A per-session memory module |
| Object leaves the view | Keeps segmenting after it returns | Tracks it even if it temporarily leaves view |
| Long videos | Limited GPU memory use; repository reports about 20 FPS, hardware dependent | Processes frames one at a time with streaming inference |
For the SAM 2 workflow in Supervisely, read the SAM 2 guide.
When does XMem fail? Limitations
Neural network XMem for masks tracking sometimes fails when the target object moves too quickly or has severe motion blur. So even the sensory memory — the fastest memory block in the model architecture cannot catch up with fast object changes. Also, one of the additional failure cases is the fast motion with similarly-looking objects that do not provide sufficient appearance clues for XMem to track.
Conclusion
In this tutorial, you learned how to perform efficient video object segmentation using two models.
-
The first model — Segment Anything is used to quickly segment objects on the first frame.
-
XMem model is used to track these masks on the next frames.
As you can see, Supervisely Video Labeling Toolbox and the Ecosystem of Apps can help you annotate videos for your custom training datasets. Try it yourself in our free Community Edition version.
Frequently asked questions
What is video object segmentation (VOS)?
Video object segmentation highlights all pixels of specific target objects in every frame of a video. In the semi-supervised setting you annotate the objects on the first frame and the network segments and tracks them in the next frames.
What is XMem?
XMem is a class-agnostic video object segmentation architecture for long videos with unified feature memory stores. It was introduced at ECCV 2022 and can track masks for any object, including objects that leave the scene for a while.
Why combine Segment Anything with XMem?
XMem needs a mask to start from. Segment Anything, an interactive segmentation model, creates that mask on the first frame from clicks or a box, and XMem then predicts the mask on the next frames.
Do I need a GPU to run XMem in Supervisely?
Yes. Both models run as Supervisely Apps on a computer with a GPU that you connect to your account once with a single terminal command. You can connect several computers to scale up.
When does XMem fail?
It can fail when the target moves very fast or has severe motion blur, and when similar-looking objects move fast, because there are not enough appearance clues to tell them apart. Check the masks and correct them manually.
Is there a newer model that segments and tracks in one step?
Yes, Segment Anything 2 handles segmentation and tracking in one model. See our SAM 2 guide for how to use it in Supervisely.