OpenAI CLIP for Image Retrieval: Filter a Dataset by Text Prompt
 Max Kolomeychenko
Type a text prompt and find the most relevant images in a large training dataset. See how CLIP embeddings work and filter images with a UI in Supervisely.
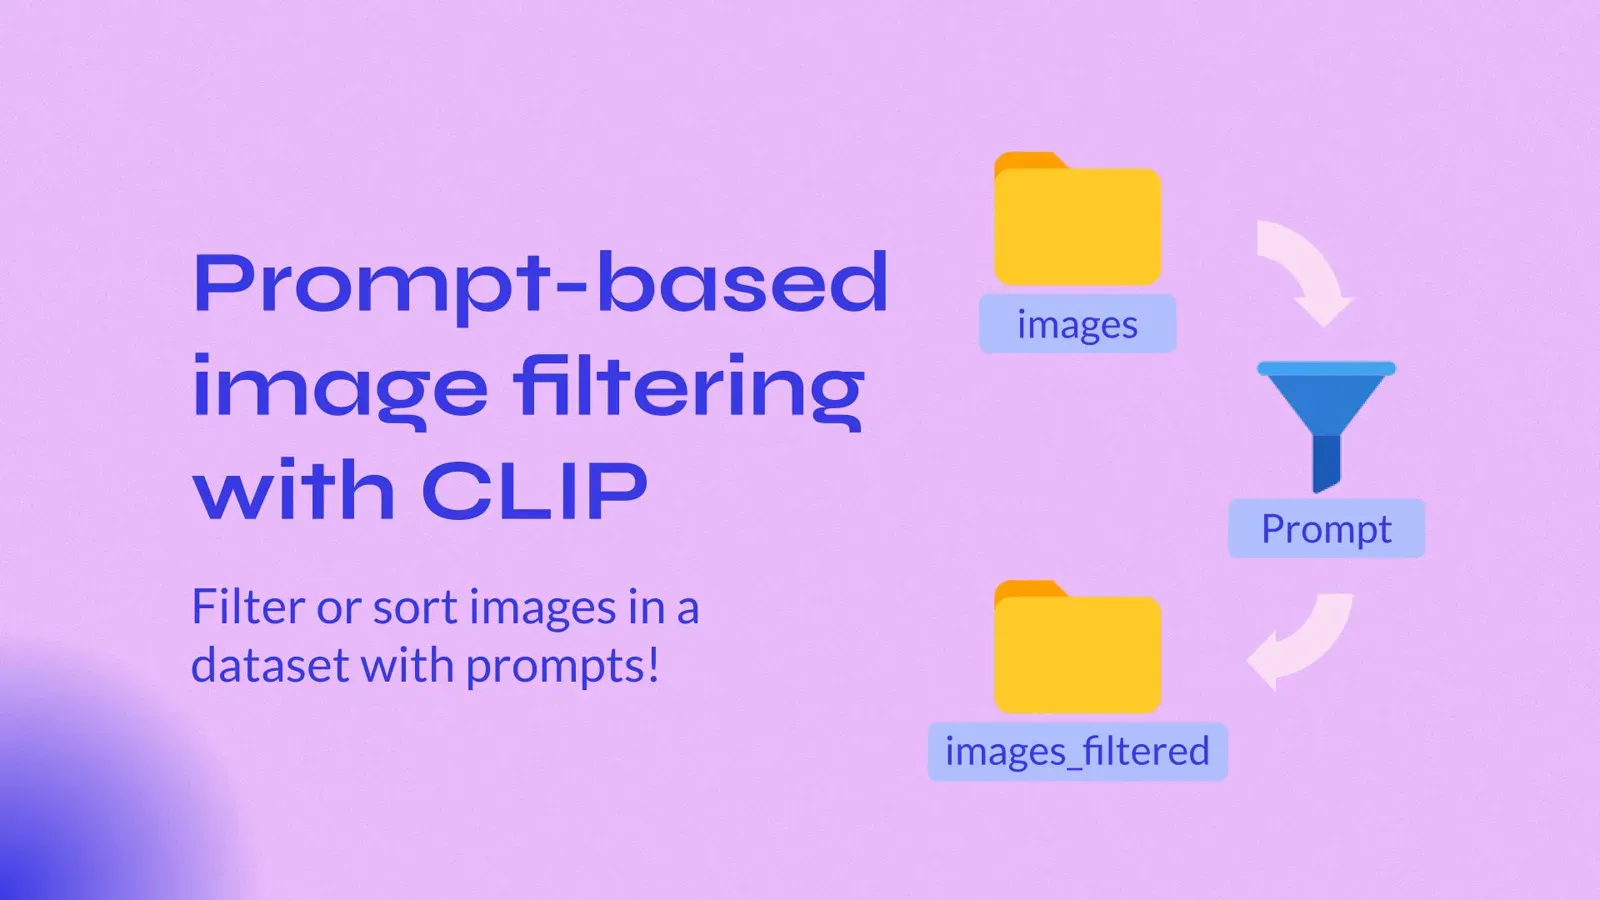
Image retrieval is the task of searching, filtering and querying large image collections, for example with a text prompt. OpenAI's CLIP model does this by turning text and images into embeddings and comparing them. This guide shows how to run CLIP in Supervisely to sample relevant images from your computer vision datasets, next to the platform's query and filter tools.
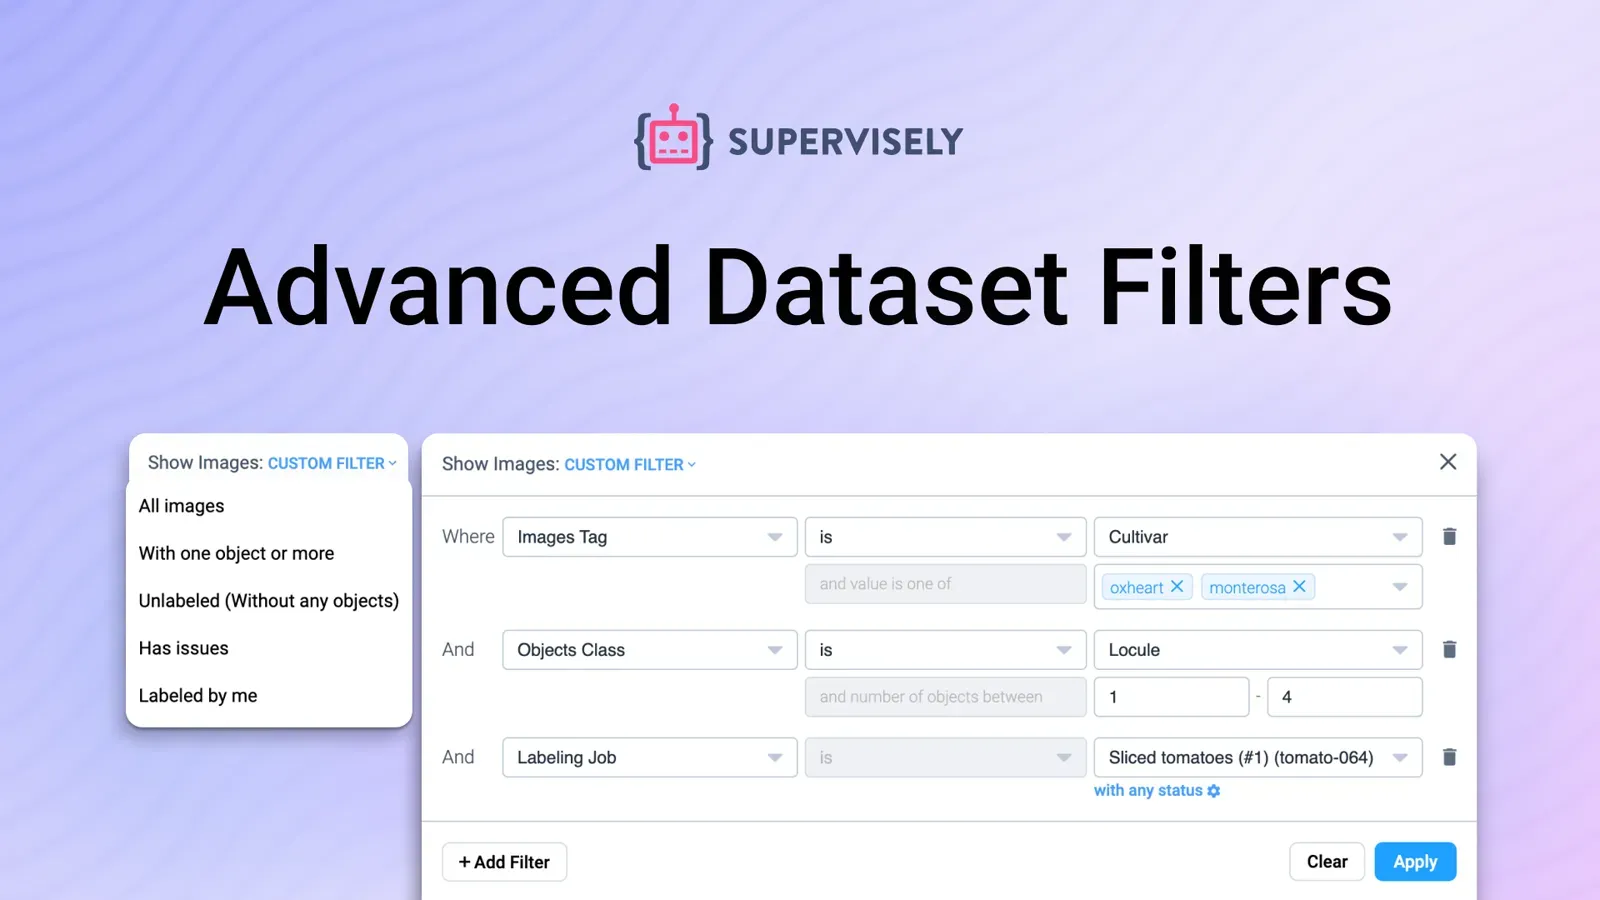
Training datasets can hold thousands or millions of images, so retrieval helps you find the ones you need. The app below comes from the Supervisely Ecosystem. For rule-based filtering instead of text prompts, see advanced dataset filters. Dataset handling is described in the docs.
Video tutorial
In this video we explain how to use the OpenAI CLIP model in Supervisely to filter custom datasets in 5 steps:
-
Run Supervisely App "Prompt-based Image Filtering with CLIP" from the context menu of your project with images.
-
Select a dataset.
-
Define a text prompt.
-
Sort and browse the most relevant images based on the similarity between the text query and image content.
-
Manage a dataset by defining the threshold to filter and move images to another dataset or project.
What is Image Retrieval?
Image retrieval is a computer vision task of browsing, searching, filtering and querying from large datasets of images. Nowadays Neural Networks are used for this task, especially in the cases where the images are unlabeled. A familiar example is web image search. A user just provides text query (text prompt) and image retrieval system searches and shows the most relevant images in the entire database. Sometimes it is also called a semantic image search engine.
Automatic tools for smart image filtering and querying can be effectively used during Computer Vision research. For example, in training data annotation. Images can be subsampled based on the text prompt to quickly find unique edge cases and improve training data diversity. CLIP from OpenAI is a common choice for these tasks.
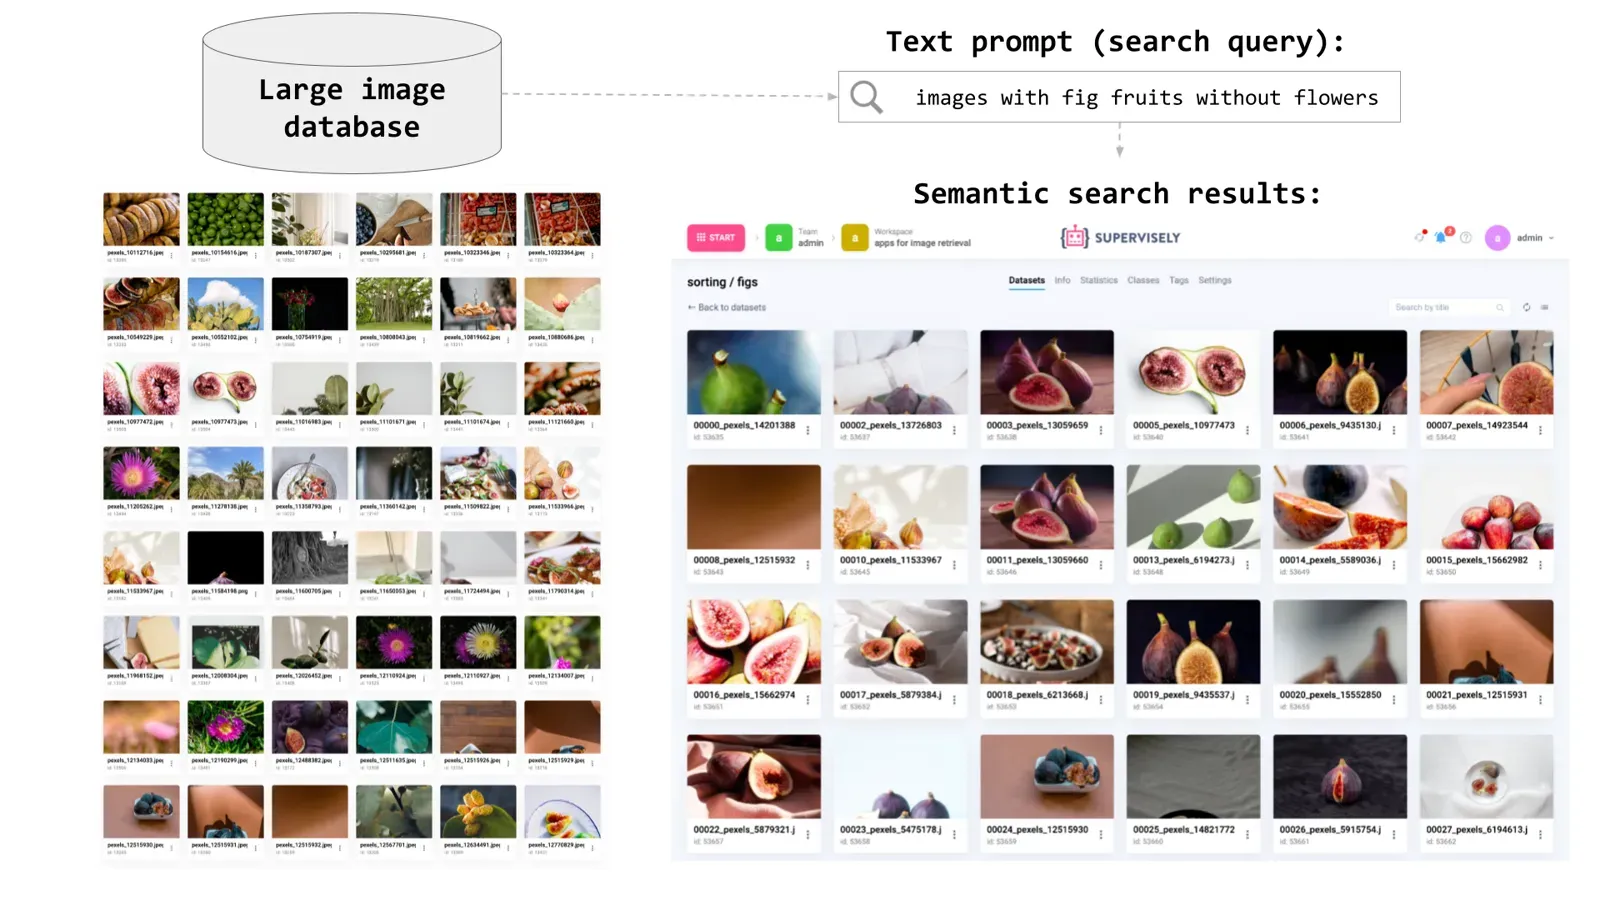 Simple scheme chat explains how Image Retrieval systems work
What is the OpenAI CLIP model?
OpenAI's CLIP (Contrastive Language-Image Pre-Training) is a neural network trained on 400 million (image, text) pairs collected from the internet (paper). The code and weights are open source under the MIT license. In the paper, CLIP is competitive with fully supervised baselines on many classification benchmarks in a "zero-shot" setting, with no training or fine-tuning step.
Here is a simple explanation of how the CLIP model is used for searching and filtering relevant images in Computer Vision datasets. The CLIP model takes text as input and produces the embedding (the vector of N numbers). Also, it can take images as input and again produce the embeddings. So the model outputs the embedding from the input text or image.
What does that mean? Embeddings allow us to compare similarity scores between texts and/or images. Mathematically, the CLIP model just smartly maps (transforms) texts and images to points in N-dimensional space. Thus we can calculate the distance between them - how close these points are to each other. Often, this distance is called a relevance score - how the pair text-text, image-image or text-image are relevant to each other. Sometimes it is called confidence - how the model is confident that the text and image (input pair) are relevant to each other and represent the same concept.
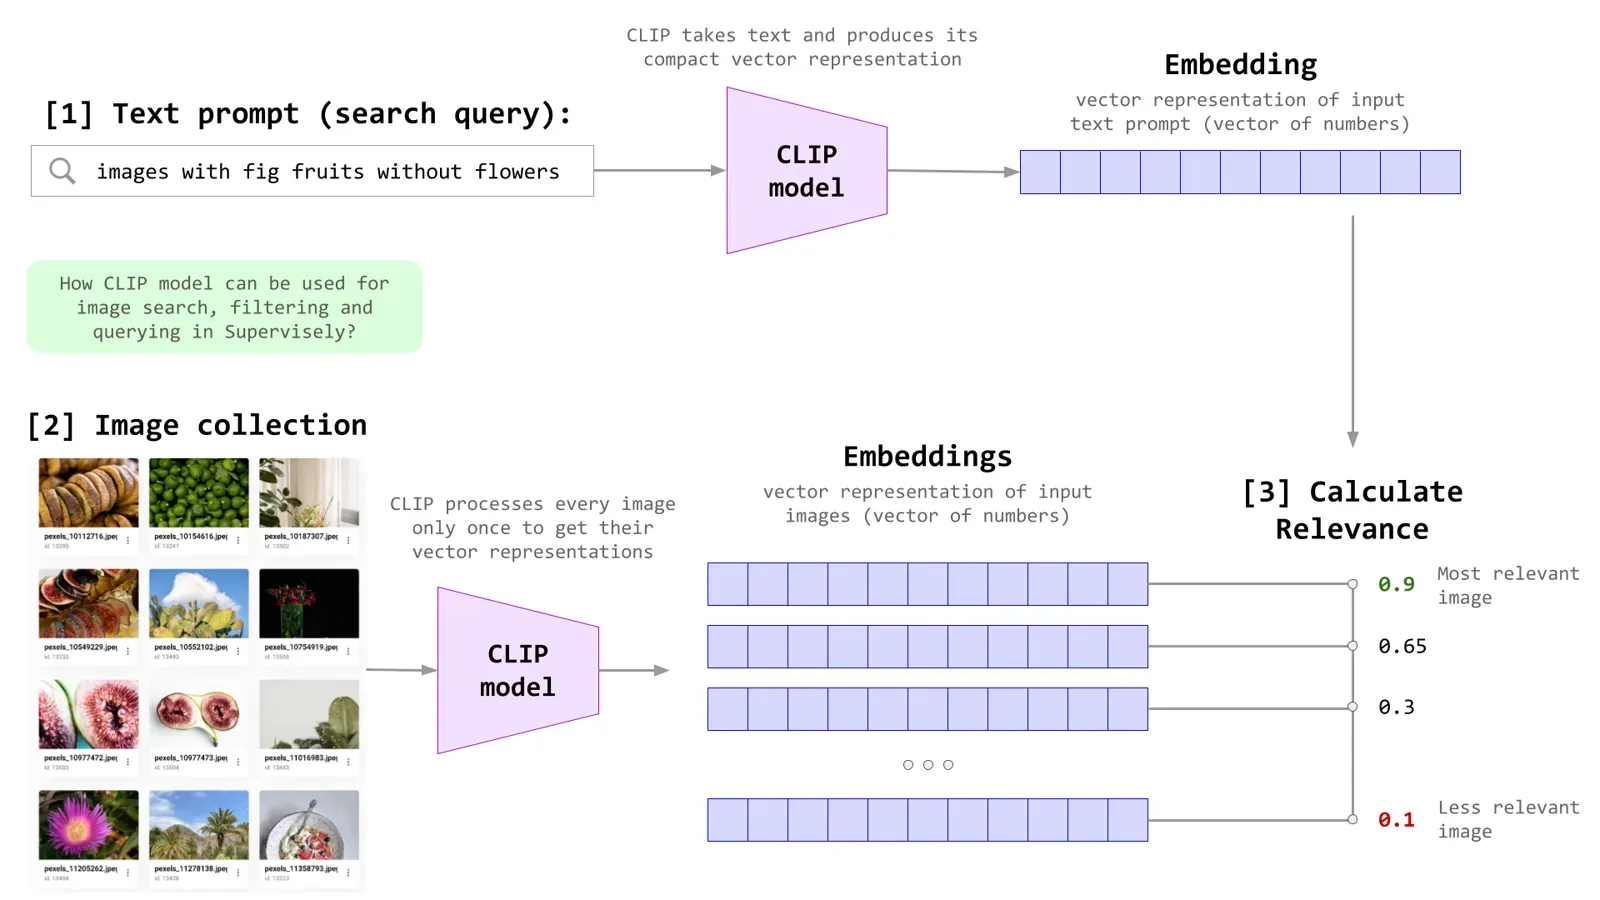 Image retrieval with CLIP model. This scheme is used in Supervisely App ("Prompt-based Image Filtering with CLIP") for filtering and querying images in custom datasets.
CLIP has limits. The paper reports it recognizes many common objects well, but it struggles with more abstract and systematic tasks, such as counting objects or estimating distance. It is also weak at general text recognition (OCR).
The CLIP model and its weights are often used as a core part of other Neural Network architectures because it transfers well to other tasks.
How to use CLIP for image filtering?

Prompt-based Image Filtering with CLIP
Filter and rank images by text prompts with CLIP models
This Supervisely App - Prompt-based Image Filtering with CLIP lets you use the CLIP model through a GUI.
-
Initial step. You need to connect your computer with GPU to your account if you haven't done it yet. Watch the video guide on how to do that (MacOS, Ubuntu, any Unix OS or Windows).
-
Run the app from a context menu of your project or directly from Supervisely Ecosystem.
-
Define text prompt and run calculations
-
Browse search results and the most relevant images
-
Configure filtering settings and export results to another dataset.
CLIP prompts vs rule-based filters: when to use each?
Use a text prompt when images are unlabeled or you look for a concept ("a night street", "a rusty pipe"). Use rule-based filters when the images already carry classes, tags or statuses. The two work well together.
| CLIP text prompt | Rule-based filters | |
|---|---|---|
| Needs labels | No | For conditions on classes, tags, authors or job status |
| You describe the target with | A free text prompt | Conditions on images and annotations |
| Result | Images sorted by relevance, cut by a threshold | Exact matches |
| Guide | This post | Advanced dataset filters |
Conclusion
CLIP lets you search a training dataset with a text prompt. The Supervisely App wraps it in a GUI, so you can sort by relevance and move matching images to another dataset. Try it in the free Community Edition.
Frequently asked questions
What is image retrieval?
Image retrieval is the computer vision task of browsing, searching, filtering and querying large collections of images. A user gives a text query and the system shows the most relevant images in the whole database. It is sometimes called a semantic image search engine.
What is OpenAI CLIP?
CLIP (Contrastive Language-Image Pre-Training) is an open-source neural network trained on 400 million image-text pairs from the internet. It maps texts and images to embeddings, so you can compare how relevant a text and an image are to each other. It works in a zero-shot scenario, without a training or finetuning step.
How do I filter a dataset with CLIP in Supervisely?
Run the Prompt-based Image Filtering with CLIP app from the context menu of your project, select a dataset, define a text prompt, browse the images sorted by relevance, then set a threshold and move the matching images to another dataset or project.
Why use image retrieval for training data?
You can subsample images by a text prompt to find unique edge cases quickly and improve the diversity of your training data, even when the images are unlabeled.
What are the limits of CLIP?
CLIP recognizes common objects well, but it struggles with abstract concepts and systematic tasks. It performs poorly at measuring the distance between two objects, counting cars or pedestrians in a photo, and general text recognition (OCR).
Do I need a GPU?
Yes. You connect a computer with a GPU to your Supervisely account once, then run the app on it. Video guides cover macOS, Ubuntu, other Unix systems and Windows.