Inter-Annotator Agreement: Metrics and Consensus Labeling
 Max KolomeychenkoUpdated
Inter-annotator agreement shows how consistent labelers are. Learn Cohen's kappa, Fleiss' kappa, Krippendorff's alpha and IoU, then run consensus labeling.
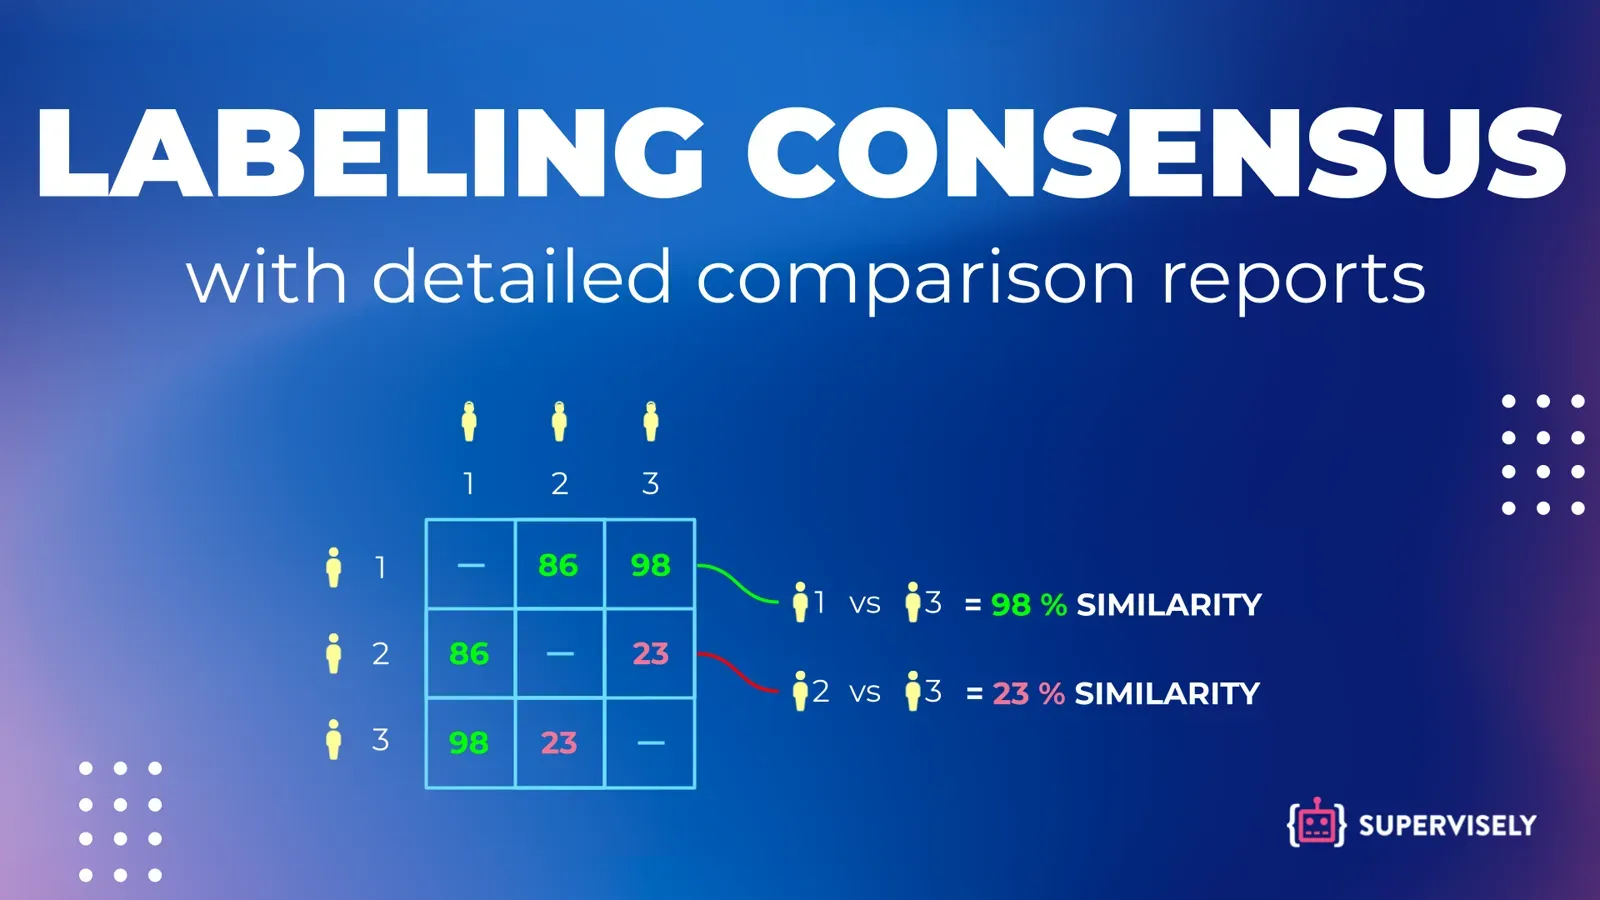
Inter-annotator agreement (IAA) measures how often independent annotators give the same label to the same data. Common metrics are Cohen's kappa (two annotators), Fleiss' kappa (three or more), Krippendorff's alpha (any number, with gaps) and IoU for boxes and masks. Supervisely's consensus app calculates pairwise agreement for you.
Consensus checks are part of data quality assurance in Supervisely. This guide first explains the metrics, then shows how to run consensus labeling on a real project.
What is inter-annotator agreement?
Inter-annotator agreement is a number that says how consistent your labelers are. Several people label the same items without seeing each other's work. You then compare their answers.
Raw percent agreement is the simplest score, but it is easy to inflate. If 90% of images contain no defect, two people who always answer "no defect" agree 90% of the time and have learned nothing. Chance-corrected metrics fix this by subtracting the agreement you would get from guessing.
Low agreement is a warning about the task, not only about the people. Typical causes are vague class definitions, unclear edge cases and different training of annotators.
Which inter-annotator agreement metrics should you use?
| Metric | Annotators | Data | What it measures |
|---|---|---|---|
| Percent agreement | 2 or more | Any | Share of items with identical labels. Ignores chance. |
| Cohen's kappa | 2 | Categorical | Agreement corrected for chance. |
| Fleiss' kappa | 3 or more | Categorical | Chance-corrected agreement for any fixed number of raters. |
| Krippendorff's alpha | 2 or more | Categorical, ordinal, numeric; gaps allowed | Observed disagreement compared to expected disagreement. |
| IoU | 2 per object | Boxes, polygons, masks | Overlap of two shapes: intersection divided by union. |
How do you calculate Cohen's kappa?
Cohen's kappa compares observed agreement with the agreement expected by chance:
kappa = (p_o - p_e) / (1 - p_e)
Here p_o is the share of items where both annotators agree, and p_e is the agreement expected from each annotator's label frequencies. For example, if p_o is 0.90 and p_e is 0.50, kappa is (0.90 - 0.50) / (1 - 0.50) = 0.80. A score of 1 means perfect agreement, and 0 means no better than chance.
Landis and Koch (1977) proposed these bands, as listed on Wikipedia: 0.00 to 0.20 slight, 0.21 to 0.40 fair, 0.41 to 0.60 moderate, 0.61 to 0.80 substantial, 0.81 to 1.00 almost perfect. The same page notes that these bands are not universally accepted.
What is Fleiss' kappa?
Fleiss' kappa extends the same idea to any fixed number of annotators. It uses the same form, kappa = (P - P_e) / (1 - P_e). P is the mean agreement over all items, and P_e is the sum of squared category proportions. See the full definition for the per-item formula. Use it when three or more people label every item.
What is Krippendorff's alpha?
Krippendorff's alpha is the most flexible metric. It handles any number of annotators, missing labels and different data types:
alpha = 1 - D_o / D_e
D_o is the observed disagreement and D_e is the disagreement expected by chance. Krippendorff's often-quoted rule, as summarized on Wikipedia, is to treat alpha of 0.800 or higher as reliable, use 0.667 to 0.800 only for tentative conclusions, and discard data below 0.667.
How do you measure agreement for boxes and masks?
Kappa works on categories. Bounding boxes, polygons and masks need a geometric measure first. Intersection over union (IoU) divides the area shared by two annotations by the area they cover together:
IoU = |A ∩ B| / |A ∪ B|
An IoU of 1 means the shapes are identical, and 0 means they do not touch. In practice you match each object from annotator A to the object from annotator B with the highest IoU, then average the scores over the image. You can also check the class label of every matched pair with kappa. Objects that one annotator drew and the other missed count as disagreement.
Why does consensus labeling matter?
Individual labelers often differ in accuracy and read the guidelines a little differently. Errors in the data also reach your models. Northcutt, Athalye and Mueller estimate at least 3.3% label errors on average across the test sets of 10 widely used datasets, and at least 6% in the ImageNet validation set.
Consensus labeling means several annotators label the same images independently, and you combine or compare their labels. Majority voting is a well-known way to combine them. It works for object detection, semantic and instance segmentation, and classification.
Agreement scores let you:
- find systematic inconsistencies early,
- compare annotators and find the most accurate ones for your task,
- improve guidelines for edge cases you did not expect.
How does consensus labeling work in Supervisely?
In Supervisely, the Labeling consensus app compares every pair of annotators on the same project and scores each pair from 0% to 100%. A score of 0% means the annotations are completely different. A score of 100% means they are identical. The app is described in the docs.
Key features:
- A consensus score for every pair of annotators, shown as a confusion matrix.
- Support for bounding boxes, masks, polygons, and image and object tags.
- A detailed report for every score, with high-level metrics and image-level differences.
- Real-time monitoring at any stage of labeling, even if it is not finished.
The app automatically matches labeled images, objects, classes and tags, and calculates metrics only on the intersection. The docs do not state the exact matching formula, so treat the 0 to 100% score as a similarity measure and use the report to see what drives it.
Here is the video tutorial:
Example: how do three annotators label insulator defects?
Three annotators label drone images with bounding boxes in three classes. The target object is an insulator, with two types of defects: pollution flashover and broken parts. The demo data comes from the Insulator-Defect Detection dataset.
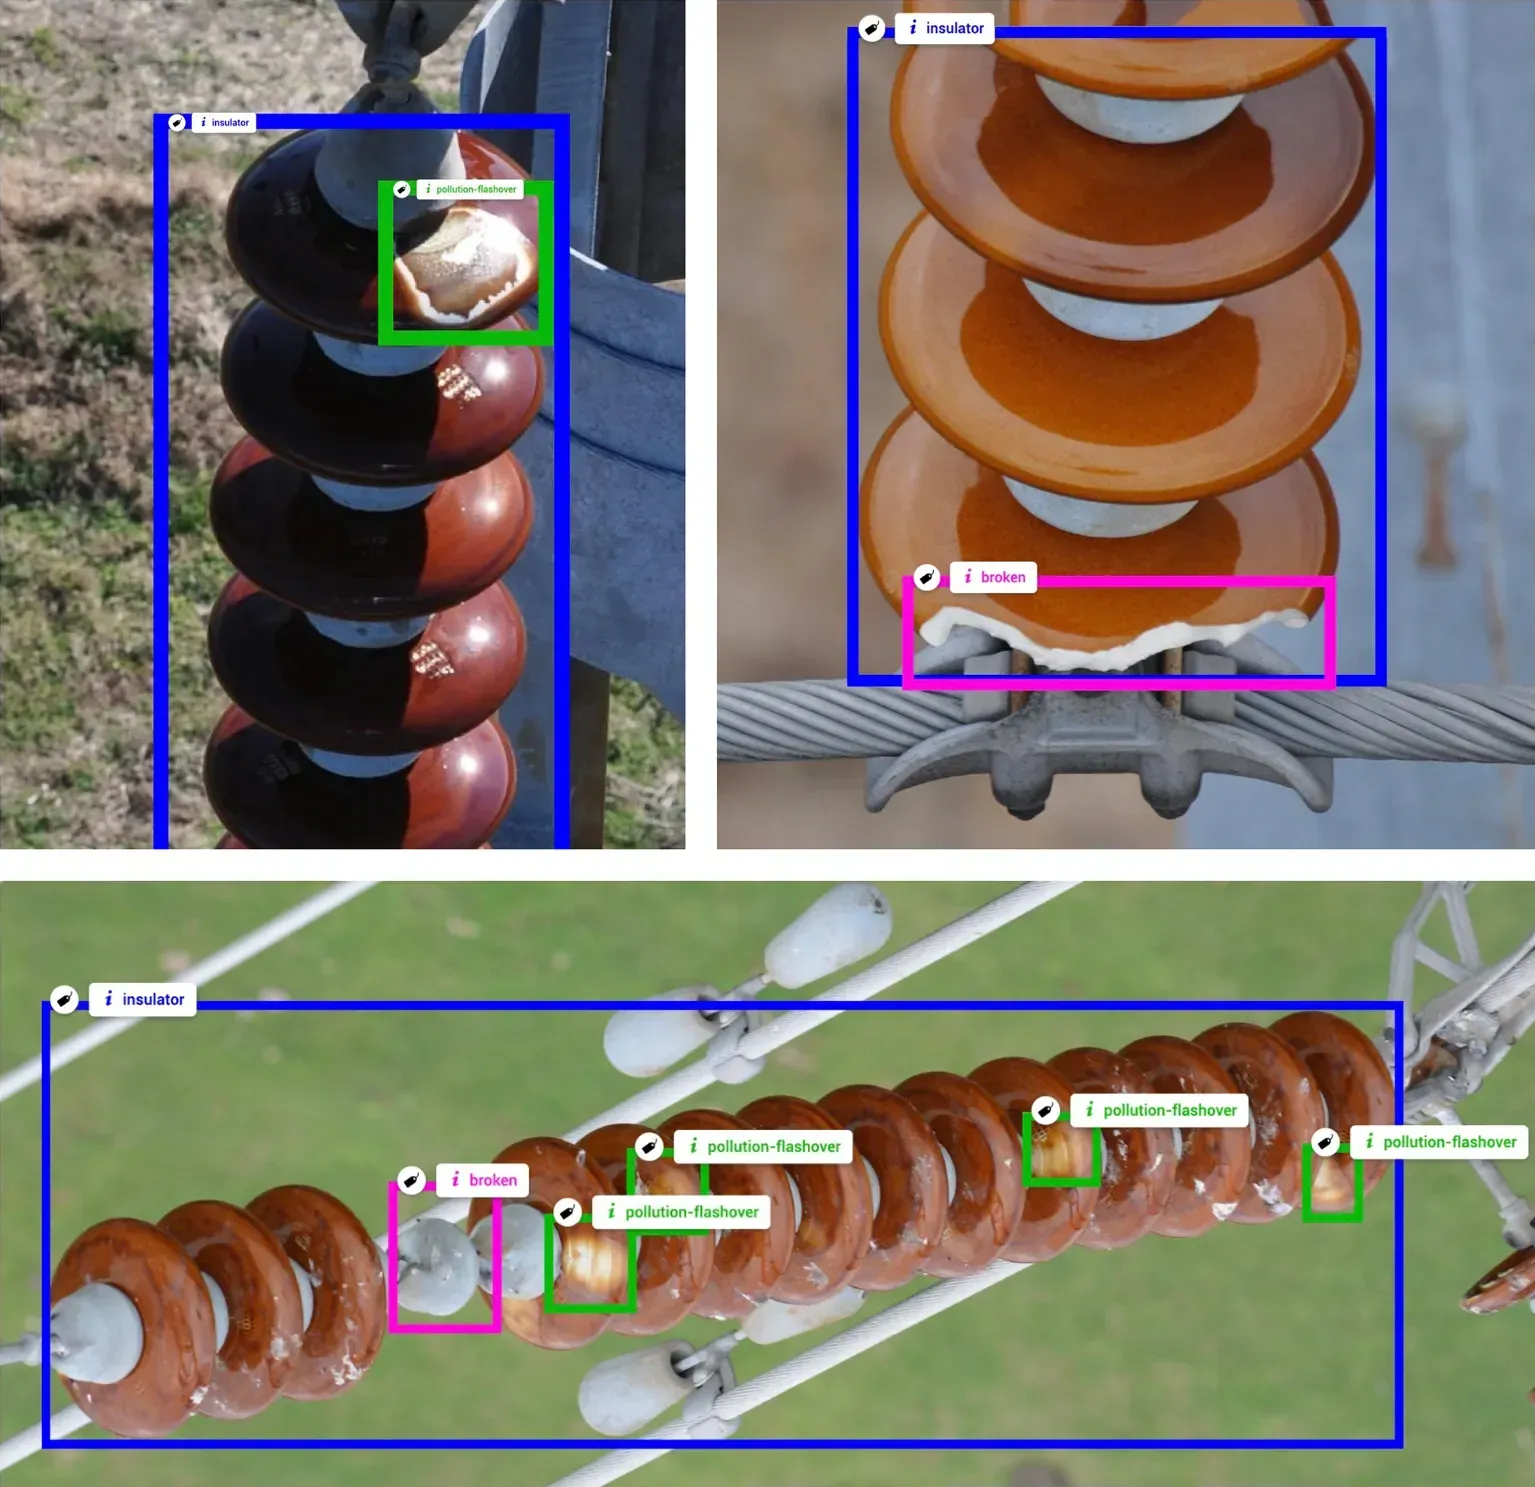 Examples of images labeled with three classes of objects: insulator, pollution flashover, broken.
How to set up simultaneous labeling
Use labeling jobs to give the same images to several annotators. Jobs are part of collaboration at scale and let managers coordinate even hundreds of team members. For a shared pool of work, see labeling queues. Per the docs, queues can also send each item to several annotators and score their agreement for image and video projects.
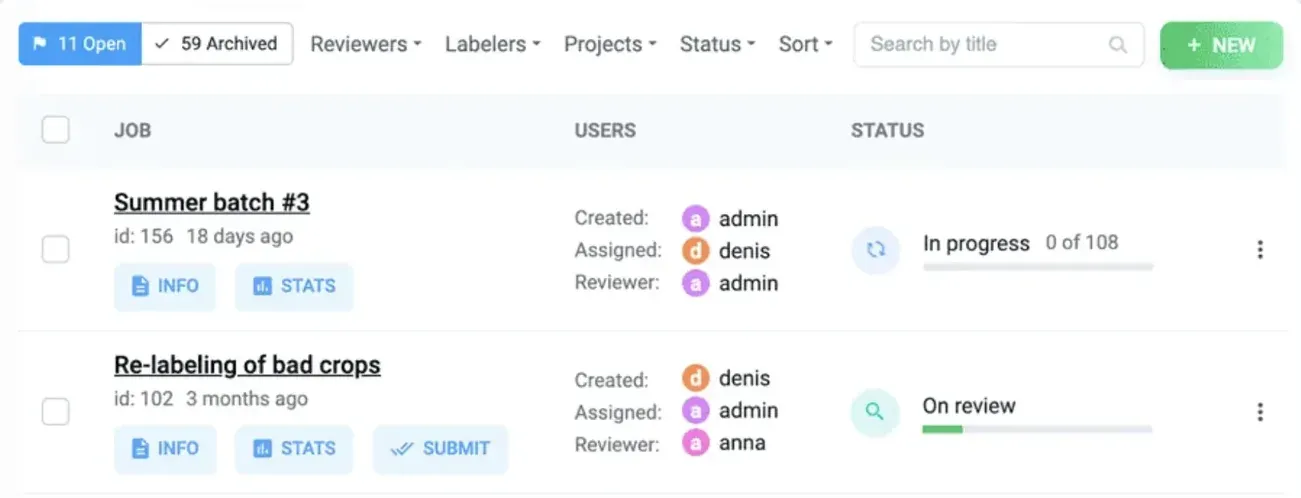 Example of labeling jobs dashboard with real-time statuses to monitor the whole labeling process efficiently
How to run the consensus app step by step
- Let several annotators label the same images independently with the same classes and tags.
- Start the app from the project context menu. You can also start it from the Supervisely Ecosystem and select the project in the first step.
- Read the confusion matrix with a score for every pair of annotators.
- Click a score to open the detailed report.
- Add the edge cases you found to the labeling guide.
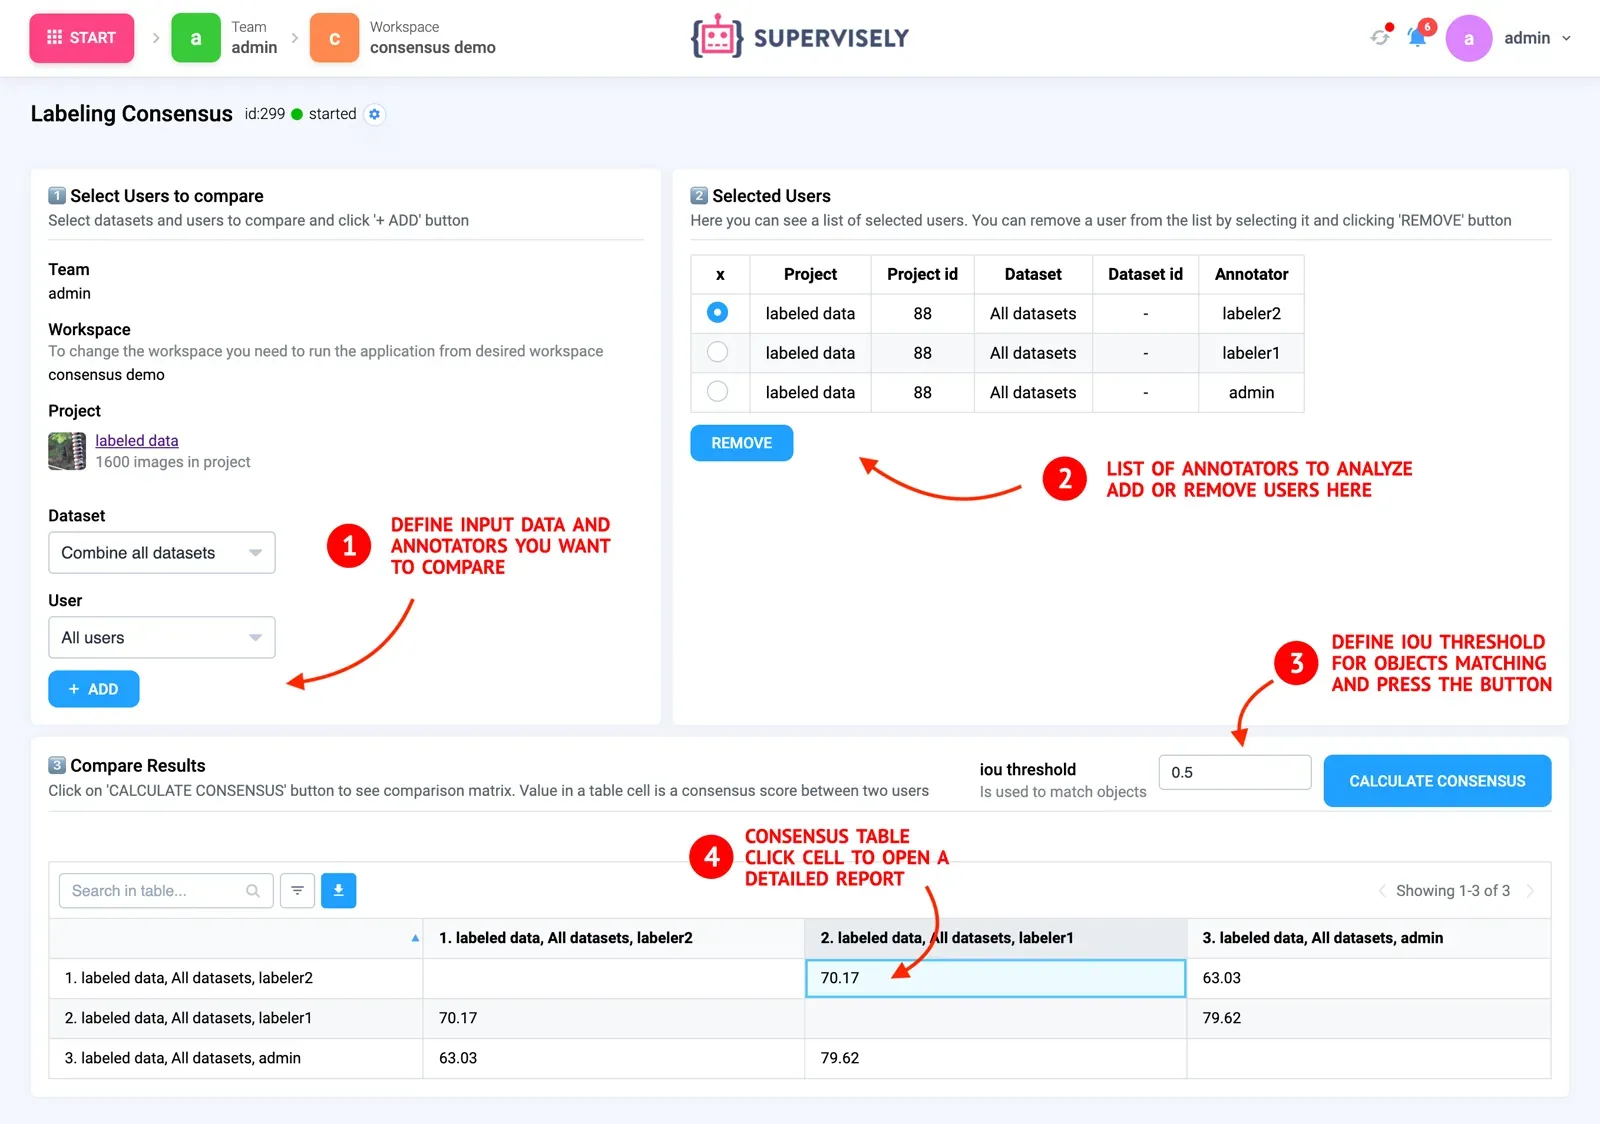 Example of the Labeling consensus app - settings and consensus table
What does a detailed consensus report show?
Say the score for a pair is 83%. That means the two annotations are 83% similar, which is useful but does not tell you where or why they differ. The report for each score lets you compare the pair's annotations image by image.
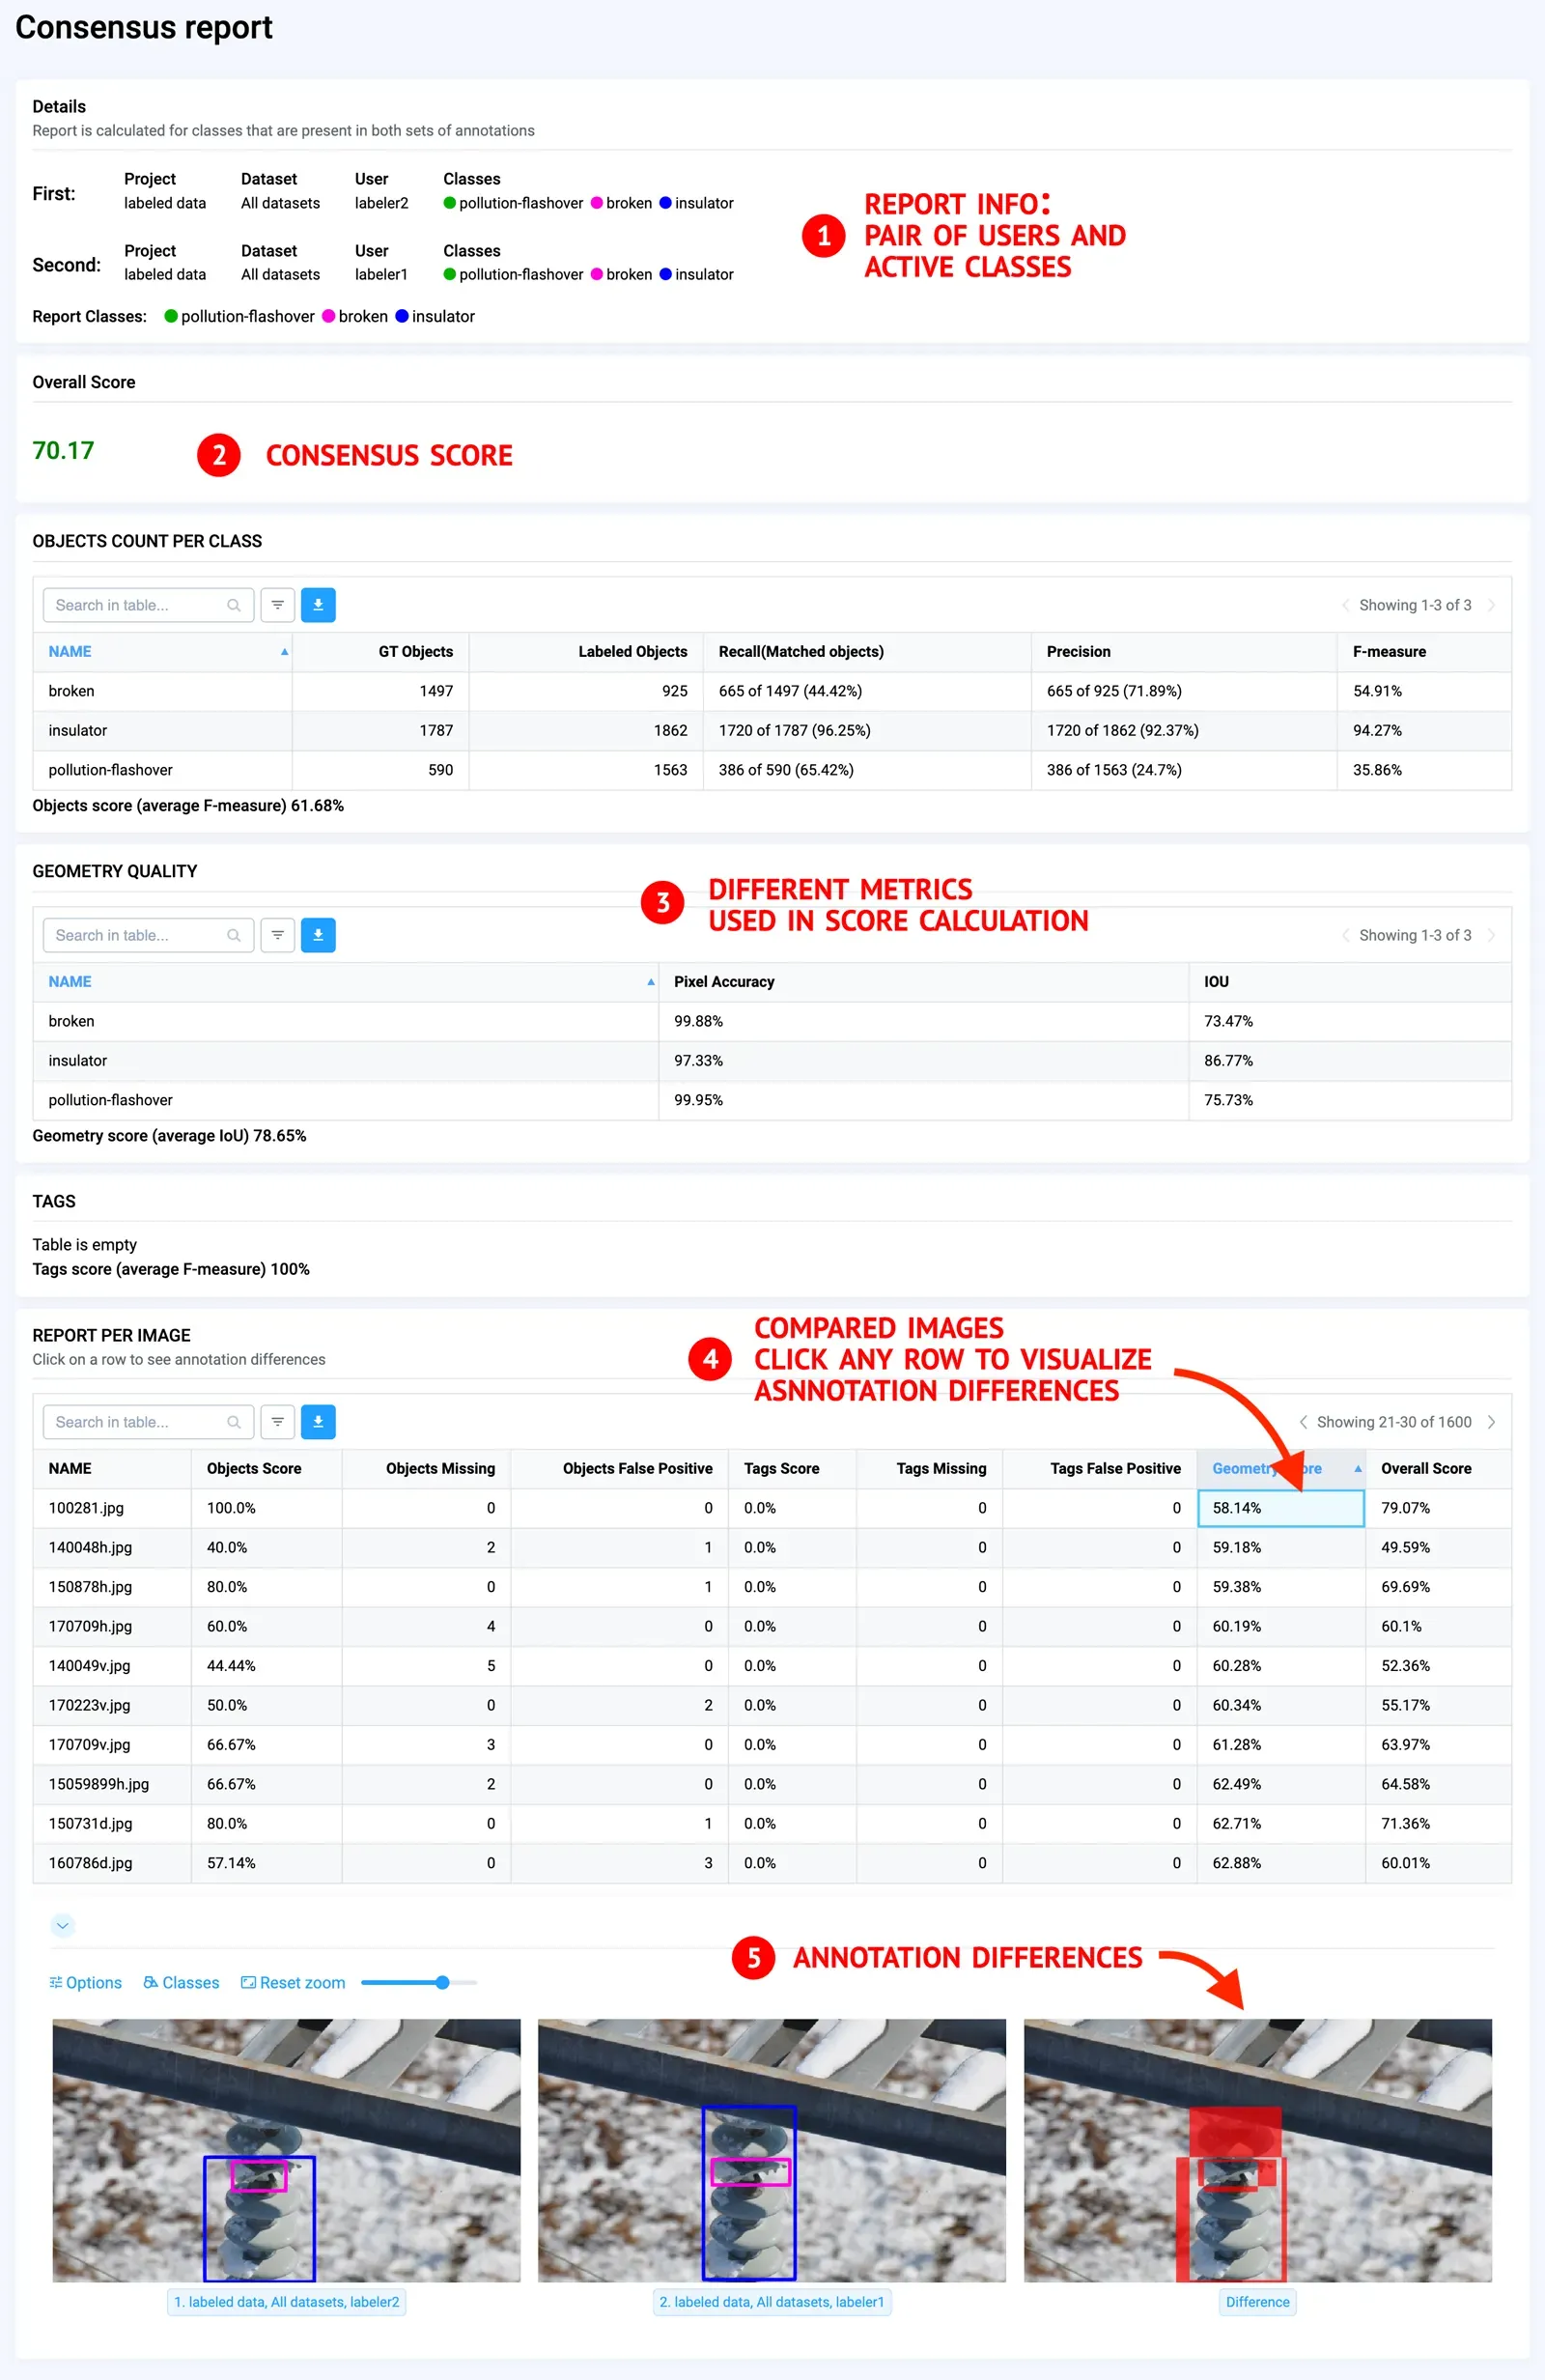 Example of consensus report for the selected pair of annotators
Use the findings to clarify the guidelines for edge cases and outliers. Then agreement improves in the next round.
How do you customize consensus labeling?
The consensus app is an open-source app written in Python. Fork the repo to build your own private version. For example, you can add steps such as removing unmatched annotations or keeping only the labels that most annotators agree on.
You do not need web development skills. The Supervisely App Engine is designed for Python developers and data scientists. Install the pip package and follow the developer portal.
Which agreement score is enough?
There is no universal target. Pick it by the cost of an error and the difficulty of the task.
| Situation | What to do |
|---|---|
| Score is high | Spot-check a sample of images, then continue labeling. |
| Score is low for one pair | Review that pair's report. One annotator may need retraining. |
| Score is low for everyone | The guidelines or classes are the problem. Rewrite them with examples. |
| Score drops over time | New data or a changed guideline. Re-run the check after each batch. |
For other dataset checks, see data QA tools and the QA checklist.
Conclusion
Run the consensus app on a working project to get pairwise agreement scores and a report for each one. Use kappa or alpha for category labels, and IoU for shapes. Low scores point to unclear guidelines, and fixing them gives you more accurate training data.
Frequently asked questions
What is inter-annotator agreement?
Inter-annotator agreement (IAA) is a score for how often independent annotators give the same label to the same item. High agreement means the guidelines are clear and the labels are consistent. Low agreement means the task is ambiguous or the labelers were trained differently.
Which IAA metric should I use?
Use Cohen's kappa for two annotators and categorical labels, Fleiss' kappa for three or more annotators, and Krippendorff's alpha when some items are missing or the labels are ordinal or numeric. For boxes, polygons and masks, use IoU between the matched objects.
What is a good Cohen's kappa score?
Landis and Koch (1977) call 0.61 to 0.80 substantial and 0.81 to 1.00 almost perfect agreement. These bands are a rule of thumb, not a standard, so set your own target per task.
What is a good Krippendorff's alpha?
Krippendorff suggests relying on data with alpha of 0.800 or more, using 0.667 to 0.800 only for tentative conclusions, and discarding data below 0.667. Check the threshold against how costly an error is in your project.
How does consensus labeling work in Supervisely?
Several annotators label the same images independently. The Labeling consensus app matches their images, objects, classes and tags, then shows a pairwise score matrix from 0 to 100 percent. Clicking a score opens a report with the differences for every image.
Which annotation types does the Supervisely consensus app support?
Bounding boxes, masks, polygons, and image and object tags. It calculates scores only on the data that annotators both labeled, so you can run it before labeling is finished.